Baseten Integrates DeepSeek-V4.1-Flash into Model APIs, Featuring 1M-Token Context – Unite.AI

Introducing DeepSeek-V4.1-Flash: Revolutionizing Model APIs on Baseten

On September 11, 2026, Baseten unveiled the DeepSeek-V4.1-Flash model, a remarkable 552B-parameter multimodal mixture-of-experts (MoE) architecture. This innovative model utilizes 8B active parameters for prefill and 16B for decoding across a vast 1M-token context window, enhancing the capabilities available on their platform. For more insights, you can read Baseten’s official announcement here.

DeepSeek has also made the model’s open weights accessible on Hugging Face, as detailed in their announcement from September 9, 2026. The model supports text and image inputs and generates textual outputs. It’s licensed under the MIT License as per the model card. Baseten describes V4.1-Flash as DeepSeek’s third open-weight release this year, featuring the exclusive Causal Encoder-Decoder design. Future support for Baseten’s Loops training product is on the horizon.

Benchmarking Results: A New Standard for Performance

The model card showcases impressive benchmark results, particularly at the highest reasoning effort setting of 100. V4.1-Flash scored 90.6 on Terminal-Bench 2.1, outperforming V4-Flash (82.7) and V4-Pro (87.9). It scored 74.2 on DeepSWE v1.1, compared to 54.4 and 62.7, and 54.8 on AutomationBench, rising above 37.7 and 43.2 for earlier models. While V4.1-Flash demonstrates superior performance with significantly fewer parameters, it’s important to note that scoring 54.8 on AutomationBench indicates it may struggle with complex workflows, emphasizing the continued need for human oversight in agent operations.

When compared to other leading models, V4.1-Flash registered 90.9 on GPQA Diamond, a Codeforces rating of 3471, and 63.9 on HLE with tools. Notably, this is DeepSeek’s first non-experimental model to handle native image input, a feature previously limited to experimental systems. Its scores of 78.9 on Chartography and 49 on ZeroBench validate its advancements against previous experimental benchmarks.

Innovative Causal Encoder-Decoder Architecture

V4.1-Flash employs a sophisticated 40-layer Transformer configured as a 20-layer causal encoder followed by a 20-layer decoder. The decoder’s global key-value (KV) cache is projected from the final encoder hidden states, enhancing efficiency. With 8B parameters activated during prefill and 16B during decoding, Baseten highlights the model’s cost-effectiveness for coding agents, where prefill tokens significantly outnumber decode tokens.

The model features Compressed Sparse Attention 2, with each layer operating in one of three static modes (Full, Reindex, or Reuse). This design, along with a Hierarchical Sparse Indexer, reduces indexing costs significantly while maintaining performance. The combined innovations cut the global KV cache size to 890 bytes per token—approximately one-quarter of the previous model. Additionally, the SWA Bounded Replay mechanism reconstructs KV states efficiently by only replaying the most recent tokens, reducing the persistent KV footprint to about one-eighth of the earlier generation.

Each MoE layer integrates one shared expert and 384 routed experts, with six experts activated for each token. Notably, the model also introduces Engram conditional memory, hosting 196B parameters alongside DSpark speculative decoding. DeepSeek developed V4.1-Flash from scratch using a 45T-token multimodal corpus, while extending context to 1M tokens after extensive training and fine-tuning processes.

Transitioning to DeepSeek API and Enhanced Service via Baseten

As DeepSeek phases out V4-Flash and V4-Flash-Vision-Exp, the previous API models will temporarily redirect to V4.1-Flash for compatibility. New API pricing took effect on September 10, 2026, with off-peak rates set at 50% of peak rates. Noteworthy partners, including WorkBuddy and OpenCode, fully support V4.1-Flash on their platforms.

Baseten’s Inference Stack efficiently serves this model with NVIDIA Dynamo and KV cache-aware routing, further optimizing request handling. V4.1-Flash will be accessible through Baseten’s Model Library, with dedicated deployments for teams requiring reserved capacity.

Starting September 14, 2026, all deepseek-v4-pro requests will reroute to V4.1-Flash at corresponding rates, a transition expected to improve performance, cost, speed, and overall runtime until V4.1-Pro is released.

Here are five FAQs regarding Baseten’s addition of DeepSeek-V4.1-Flash to Model APIs with a 1M-token context, based on the Unite.AI release:

1. What is DeepSeek-V4.1-Flash?

Answer: DeepSeek-V4.1-Flash is an advanced model integration introduced by Baseten that enhances performance by allowing for a context of up to 1 million tokens. This capability enables users to process and analyze extensive data streams more efficiently, making it particularly useful for applications requiring large datasets.

2. How does the 1M-token context improve model performance?

Answer: The 1M-token context allows the model to retain and analyze significantly more information at once, leading to better understanding and generation of text. This feature is particularly beneficial for tasks that require comprehensive context, such as conversational AI, summarization, or document examination, ultimately resulting in more coherent and relevant outputs.

3. What are the practical applications of using DeepSeek-V4.1-Flash?

Answer: DeepSeek-V4.1-Flash can be applied in various fields, including natural language processing, customer support automation, content generation, and any scenario where deep analysis of large text datasets is necessary. Its ability to handle a 1M-token context means it can support complex projects that require nuanced understanding.

4. What are the benefits of using Baseten’s Model APIs with DeepSeek integration?

Answer: Using Baseten’s Model APIs with DeepSeek integration provides users with a robust toolkit that combines ease of access to advanced AI capabilities with the opportunity to perform complex analytical tasks. The APIs enable seamless integration into existing workflows and applications, facilitating rapid development and deployment of AI solutions.

5. Is there any learning curve associated with implementing DeepSeek-V4.1-Flash?

Answer: While the integration is designed to be user-friendly, some users may need to familiarize themselves with the specifics of the DeepSeek model and its API functionalities. Baseten provides documentation and support to help developers smoothly transition and fully leverage the enhanced capabilities of DeepSeek-V4.1-Flash in their applications.

Source link

Understanding Why Language Models Struggle with Conversational Context

New Research Reveals Limitations of Large Language Models in Multi-Turn Conversations

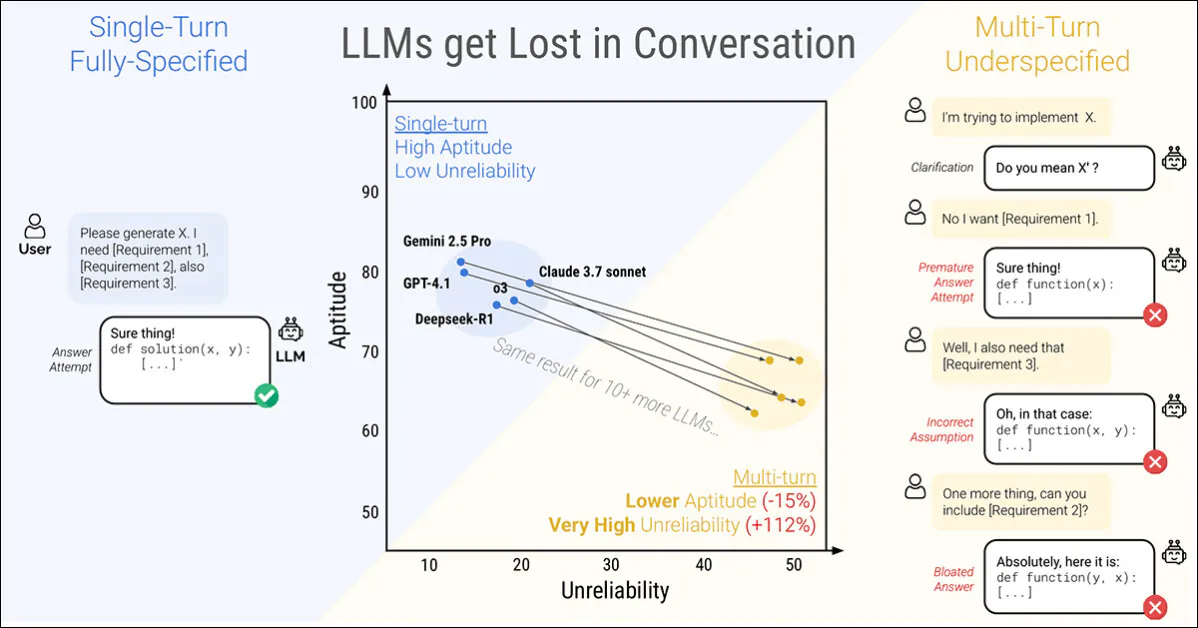
A recent study from Microsoft Research and Salesforce highlights a critical limitation in even the most advanced Large Language Models (LLMs): their performance significantly deteriorates when instructions are given in stages rather than all at once. The research found an average performance drop of 39% across six tasks when prompts are split over multiple turns:

A single turn conversation (left) obtains the best results. A multi-turn conversation (right) finds even the highest-ranked and most performant LLMs losing the effective impetus in a conversation. Source: https://arxiv.org/pdf/2505.06120

A single-turn conversation (left) yields optimal results while multi-turn interactions (right) lead to diminished effectiveness, even in top models. Source: arXiv

The study reveals that the reliability of responses drastically declines with stage-based instructions. Noteworthy models like ChatGPT-4.1 and Gemini 2.5 Pro exhibit fluctuations between near-perfect answers and significant failures depending on the phrasing of tasks, with output consistency dropping by over 50%.

Understanding the Problem: The Sharding Method

The paper presents a novel approach termed sharding, which divides comprehensive prompts into smaller fragments, presenting them one at a time throughout the conversation.

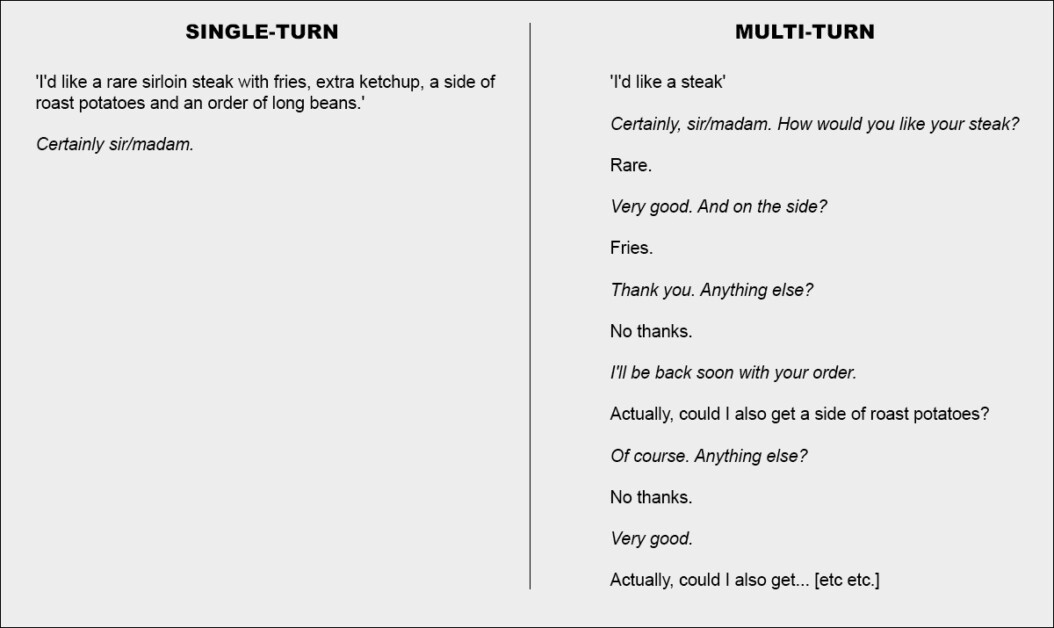
This methodology can be likened to placing a complete order at a restaurant versus engaging in a collaborative dialogue with the waiter:

Illustration of conversational dynamics in a restaurant setting.

Two extremes of conversation depicted through a restaurant scenario (illustrative purposes only).

Key Findings and Recommendations

The research indicates that LLMs tend to generate excessively long responses, clinging to misconceived insights even after their inaccuracies are evident. This behavior can lead the system to completely lose track of the conversation.

Interestingly, it has been noted, as many users have experienced, that starting a new conversation often proves to be a more effective strategy than continuing an ongoing one.

‘If a conversation with an LLM did not yield expected outcomes, collecting the same information in a new conversation can lead to vastly improved results.’

Agent Frameworks: A Double-Edged Sword

While systems like Autogen or LangChain may enhance outcomes by acting as intermediary layers between users and LLMs, the authors argue that such abstractions should not be necessary. They propose:

‘Multi-turn capabilities could be integrated directly into LLMs instead of relegated to external frameworks.’

Sharded Conversations: Experimental Setup

The study introduces the idea of breaking traditional single-turn instructions into smaller, context-driven shards. This new construct simulates dynamic, exploratory engagement patterns similar to those found in systems like ChatGPT or Google Gemini.

The simulation progresses through three entities: the assistant, the evaluated model; the user, who reveals shards; and the system, which monitors and rates the interaction. This configuration mimics real-world dialogue by allowing flexibility in how the conversation unfolds.

Insightful Simulation Scenarios

The researchers employed five distinct simulations to scrutinize model behavior under various conditions:

  • Full: The model receives the entire instruction in a single turn.
  • Sharded: The instruction is divided and provided across multiple turns.
  • Concat: Shards are consolidated into a list, removing their conversational structure.
  • Recap: All previous shards are reiterated at the end for context before a final answer.
  • Snowball: Every turn restates all prior shards for increased context visibility.

Evaluation: Tasks and Metrics

Six generation tasks were employed, including code generation and Text-to-SQL prompts from established datasets. Performance was gauged using three metrics: average performance, aptitude, and unreliability.

Contenders and Results

Fifteen models were evaluated, revealing that all showed performance degradation in simulated multi-turn settings, coining this phenomenon as Lost in Conversation. The study emphasizes that higher performance models struggled similarly, dispelling the assumption that superior models would maintain better reliability.

Conclusions and Implications

The findings underscore that exceptional single-turn performance does not equate to multi-turn reliability. This raises concerns about the real-world readiness of LLMs, urging caution against dependency on simplified benchmarks that overlook the complexities of fragmented interactions.

The authors conclude with a call to treat multi-turn ability as a fundamental skill of LLMs—one that should be prioritized instead of externalized into frameworks:

‘The degradation observed in experiments is a probable underestimation of LLM unreliability in practical applications.’

Here are five FAQs based on the topic "Why Language Models Get ‘Lost’ in Conversation":

FAQ 1: What does it mean for a language model to get ‘lost’ in conversation?

Answer: When a language model gets ‘lost’ in conversation, it fails to maintain context or coherence, leading to responses that are irrelevant or off-topic. This often occurs when the dialogue is lengthy or when it involves complex topics.


FAQ 2: What are common reasons for language models losing track in conversations?

Answer: Common reasons include:

  • Contextual Limitations: Models may not remember prior parts of the dialogue.
  • Ambiguity: Vague or unclear questions can lead to misinterpretation.
  • Complexity: Multistep reasoning or nuanced topics can confuse models.

FAQ 3: How can users help language models stay on track during conversations?

Answer: Users can:

  • Be Clear and Specific: Provide clear questions or context to guide the model.
  • Reinforce Context: Regularly remind the model of previous points in the conversation.
  • Limit Complexity: Break down complex subjects into simpler, digestible questions.

FAQ 4: Are there improvements being made to help language models maintain context better?

Answer: Yes, ongoing research focuses on enhancing context tracking in language models. Techniques include improved memory mechanisms, larger contexts for processing dialogue, and better algorithms for understanding user intent.


FAQ 5: What should I do if a language model responds inappropriately or seems confused?

Answer: If a language model seems confused, you can:

  • Rephrase Your Question: Try stating your question differently.
  • Provide Additional Context: Offering more information may help clarify your intent.
  • Redirect the Conversation: Shift to a new topic if the model is persistently off-track.

Source link

Guide for Developers on Claude’s Model Context Protocol (MCP)

Unlock Seamless AI Communication with Anthropic’s Model Context Protocol (MCP)

Anthropic’s groundbreaking Model Context Protocol (MCP) revolutionizes the way AI assistants communicate with data sources. This open-source protocol establishes secure, two-way connections between AI applications and databases, APIs, and enterprise tools. By implementing a client-server architecture, MCP streamlines the interaction process, eliminating the need for custom integrations each time a new data source is added.

Discover the Key Components of MCP:

– Hosts: AI applications initiating connections (e.g., Claude Desktop).
– Clients: Systems maintaining one-to-one connections within host applications.
– Servers: Systems providing context, tools, and prompts to clients.

Why Choose MCP for Seamless Integration?

Traditionally, integrating AI models with various data sources required intricate custom code and solutions. MCP replaces this fragmented approach with a standardized protocol, simplifying development and reducing maintenance overhead. Enhance AI Capabilities with MCP:

By granting AI models seamless access to diverse data sources, MCP empowers them to generate more accurate and relevant responses. This is especially advantageous for tasks requiring real-time data or specialized information. Prioritize Security with MCP:

Designed with security at its core, MCP ensures servers maintain control over their resources, eliminating the need to expose sensitive API keys to AI providers. The protocol establishes clear system boundaries, guaranteeing controlled and auditable data access.

Foster Collaboration with MCP:

As an open-source initiative, MCP thrives on contributions from the developer community. This collaborative setting fuels innovation and expands the array of available connectors and tools.

Delve into MCP’s Functionality:

MCP adheres to a client-server architecture, enabling host applications to seamlessly interact with multiple servers. Components include MCP Hosts, MCP Clients, MCP Servers, local resources, and remote resources.

Embark on Your MCP Journey:

– Install Pre-Built MCP Servers via the Claude Desktop app.
– Configure the Host Application and integrate desired MCP servers.
– Develop Custom MCP Servers using the provided SDKs.
– Connect and Test the AI application with the MCP server to begin experimentation.

Unveil the Inner Workings of MCP:

Explore how AI applications like Claude Desktop communicate and exchange data through MCP’s processes. Initiatives such as Server Discovery, Protocol Handshake, and Interaction Flow propel efficient communication and data exchange within MCP.

Witness MCP’s Versatility in Action:

From software development to data analysis and enterprise automation, MCP facilitates seamless integration with various tools and resources. Benefit from Modularity, Scalability, and Interoperability offered by the MCP architecture.

Join the MCP Ecosystem:

Companies like Replit and Codeium have embraced MCP, while industry pioneers like Block and Apollo have implemented it. The evolving ecosystem symbolizes robust industry support and a promising future for MCP.

Engage with Additional Resources:

To deepen your understanding, explore resources and further reading materials related to MCP. In conclusion, MCP serves as a pivotal tool in simplifying AI interactions with data sources, accelerating development, and amplifying AI capabilities. Experience the power of AI with Anthropic’s groundbreaking Model Context Protocol (MCP).

  1. What is Claude’s Model Context Protocol (MCP)?
    Claude’s Model Context Protocol (MCP) is a framework for defining data models and their relationships in a concise and standardized way, making it easier for developers to understand and work with complex data structures.

  2. How does MCP help developers in their work?
    MCP helps developers by providing a clear and consistent structure for organizing data models, making it easier to communicate and collaborate on development projects. It also promotes reusability and extensibility of data models, saving developers time and effort in building and maintaining complex systems.

  3. Can MCP be used with different programming languages?
    Yes, MCP is language-agnostic and can be used with any programming language or database system. Its flexibility allows developers to define data models in a way that suits their specific needs and preferences.

  4. How can developers get started with using MCP?
    Developers can start using MCP by familiarizing themselves with the concepts and syntax outlined in the MCP Developer’s Guide. They can then begin defining their data models using the MCP framework and incorporating them into their development projects.

  5. Is MCP suitable for small-scale projects as well as large-scale enterprise applications?
    Yes, MCP can be used for projects of any size and complexity. Whether you are building a simple mobile app or a complex enterprise system, MCP can help you define and organize your data models in a way that promotes scalability, maintainability, and long-term flexibility.

Source link

LongWriter: Unlocking 10,000+ Word Generation with Long Context LLMs

Breaking the Limit: LongWriter Redefines the Output Length of LLMs

Overcoming Boundaries: The Challenge of Generating Lengthy Outputs

Recent advancements in long-context large language models (LLMs) have revolutionized text generation capabilities, allowing them to process extensive inputs with ease. However, despite this progress, current LLMs struggle to produce outputs that exceed even a modest length of 2,000 words. LongWriter sheds light on this limitation and offers a groundbreaking solution to unlock the true potential of these models.

AgentWrite: A Game-Changer in Text Generation

To tackle the output length constraint of existing LLMs, LongWriter introduces AgentWrite, a cutting-edge agent-based pipeline that breaks down ultra-long generation tasks into manageable subtasks. By leveraging off-the-shelf LLMs, LongWriter’s AgentWrite empowers models to generate coherent outputs exceeding 20,000 words, marking a significant breakthrough in the field of text generation.

Unleashing the Power of LongWriter-6k Dataset

Through the development of the LongWriter-6k dataset, LongWriter successfully scales the output length of current LLMs to over 10,000 words while maintaining high-quality outputs. By incorporating this dataset into model training, LongWriter pioneers a new approach to extend the output window size of LLMs, ushering in a new era of text generation capabilities.

The Future of Text Generation: LongWriter’s Impact

LongWriter’s innovative framework not only addresses the output length limitations of current LLMs but also sets a new standard for long-form text generation. With AgentWrite and the LongWriter-6k dataset at its core, LongWriter paves the way for enhanced text generation models that can deliver extended, structured outputs with unparalleled quality.

  1. What is LongWriter?
    LongWriter is a cutting-edge language model that leverages Long Context LLMs (Large Language Models) to generate written content of 10,000+ words in length.

  2. How does LongWriter differ from other language models?
    LongWriter sets itself apart by specializing in long-form content generation, allowing users to produce lengthy and detailed pieces of writing on a wide range of topics.

  3. Can LongWriter be used for all types of writing projects?
    Yes, LongWriter is versatile and can be used for a variety of writing projects, including essays, reports, articles, and more.

  4. How accurate is the content generated by LongWriter?
    LongWriter strives to produce high-quality and coherent content, but like all language models, there may be inaccuracies or errors present in the generated text. It is recommended that users review and revise the content as needed.

  5. How can I access LongWriter?
    LongWriter can be accessed through various online platforms or tools that offer access to Long Context LLMs for content generation.

Source link