Understanding SGD and Adam: Optimization Algorithms for Modern AI
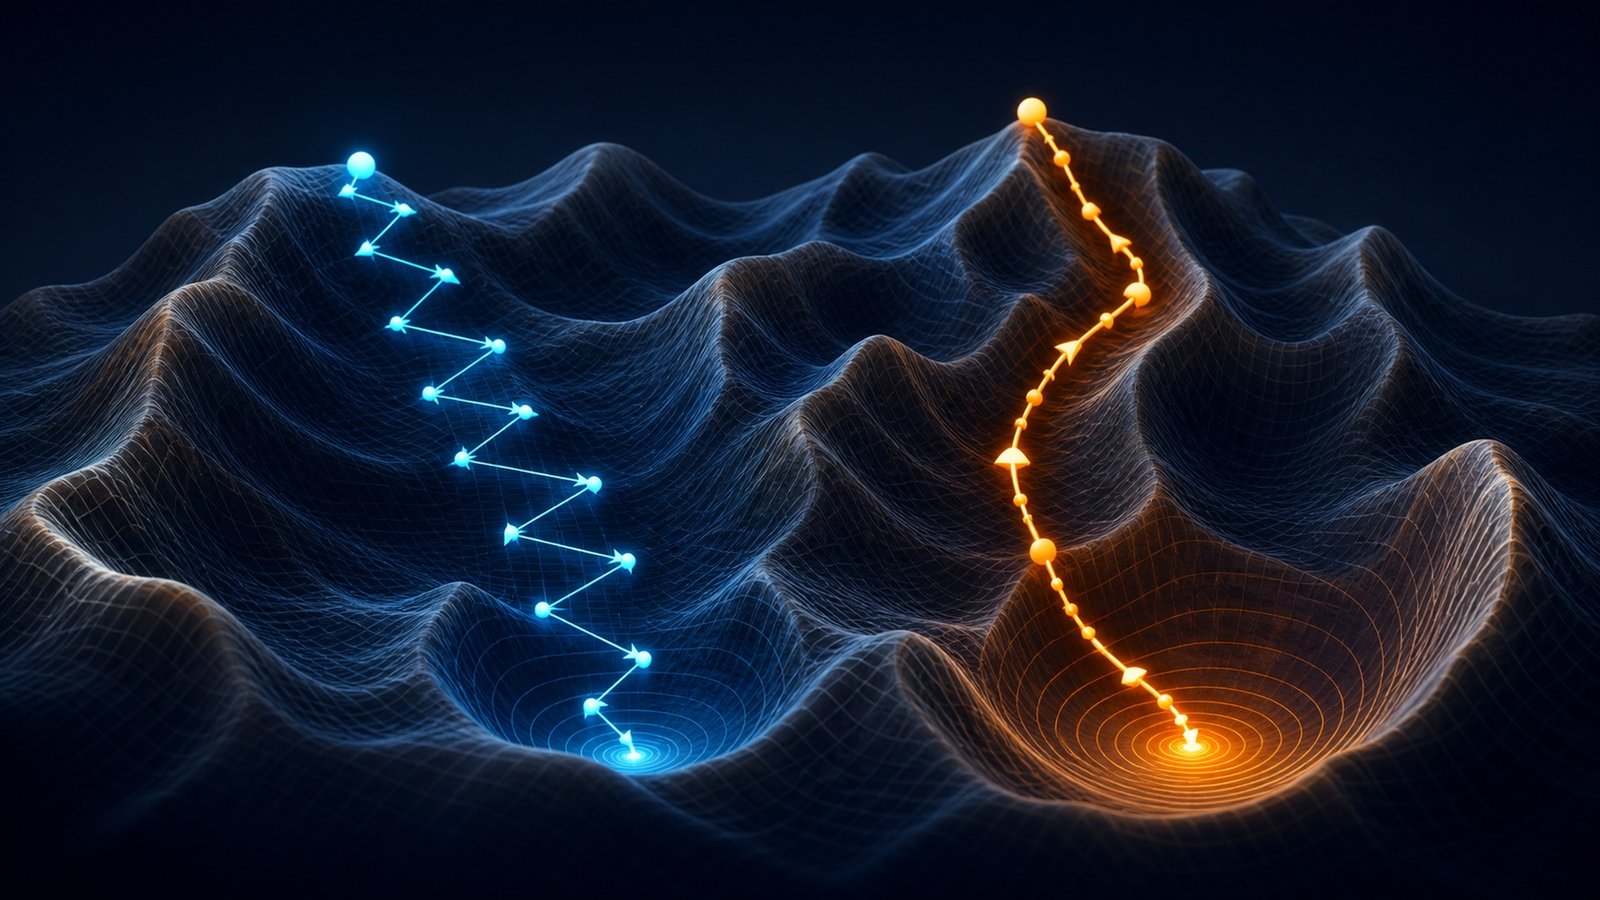
Stochastic Gradient Descent (SGD) and Adam are key optimization algorithms that enable model parameters to be updated based on estimated gradients. While both methodologies serve similar purposes, they employ distinct rules for momentum and per-parameter step sizes. This article aims to clarify their unique mechanisms, highlight common misconceptions, and provide a structured overview of their operational framework.
Defining SGD and Adam: A Closer Look
SGD and Adam stand out due to their specific workflows, which can be broken down into three fundamental components: identifiable inputs, unique transformation processes, and measurable outcomes. If any of these components are lacking, the term may refer to an intention rather than an effective implementation.
In the world of statistical learning, finite samples are transformed into predictions about future data. Consequently, aspects like optimization, regularization, and monitoring are interconnected under a single generalization problem. Understanding this integrated view—especially with algorithms like SGD and Adam—is crucial, as performance can be influenced by various factors beyond the model itself.
A Structured Five-Stage Map of SGD and Adam Operations
01Sample a mini-batch and compute
02Backpropagate gradients
03Accumulate momentum estimates
04Apply the optimizer’s parameter update
05Adjust the learning-rate schedule and repeat
1. Sampling a Mini-Batch and Computing Loss
At the initial stage, both SGD and Adam sample a mini-batch to compute loss. It is essential to analyze not just whether this operation occurs but also what information is utilized and the validity of the changes made. Reviewers should clearly differentiate this operation from other methods that evaluate complete models without gradients.
2. Backpropagating Gradients
This step involves backpropagating the calculated gradients, again emphasizing the need for careful scrutiny of the consumed data and the resulting state changes. Potential caveats should be tracked to assess the effectiveness of Adam versus SGD under various conditions.
3. Accumulating Momentum or Moment Estimates
In this phase, the system accumulates momentum estimates based on the gradients. It is crucial to ensure accurate data collection to determine how effectively the system performs compared to other optimization approaches.
4. Applying the Optimizer’s Parameter Update
Once momentum is accumulated, the optimizer’s parameter updates are applied. This step should again be assessed for its distinctiveness and the evidence validating its effectiveness. The ability to adjust strategies based on observed results is critical at this juncture.
5. Adjusting the Learning-Rate Schedule and Repeating
Finally, the system must readjust the learning-rate schedule before repeating the optimization process. The scrutiny during this stage can provide insights into managing long-term performance metrics effectively.
Concrete Example of SGD and Adam Implementation
Consider a vision model that utilizes AdamW for stable early training or momentum SGD with a meticulously crafted schedule. By focusing on observable inputs and intermediate states, we can rigorously evaluate the performance of SGD and Adam under various scenarios.
Addressing Common Misunderstandings of SGD and Adam
Often, SGD and Adam are inaccurately simplified to a search method that evaluates complete models without gradients. This narrow view risks obfuscating the defining boundaries of these algorithms, preventing accurate comparisons between products and leading to misinterpretations of experimental results.
Navigating Risks and Benefits of SGD and Adam
The primary limitation lies in Adam’s potential for rapid convergence, contrasted with SGD’s capability for better generalization. Understanding these nuances is essential as they can impact operational strategies within AI systems.
The benefits of employing SGD and Adam should be expressed through measurable outcomes: improved error rates, reduced latency, and enhanced accountability. It’s not enough for these algorithms to simply yield impressive results; they must also demonstrate consistent advantages across varied circumstances.
Critical Evaluation Plan for SGD and Adam
To effectively evaluate the performance of SGD and Adam, outline the decision the outcome is meant to support. Establish a controlled environment for testing and be prepared to version all input data. It’s vital to continuously monitor and validate the implementations against credible baselines to ensure real-world viability.
Essential Questions to Consider Before Implementation
- Objective: What specific bottleneck does SGD and Adam aim to resolve?
- Mechanism: Which stage is responsible for the key transformation?
- Baseline: How does it fare against alternative methods?
- Evidence: What types of cases have been tested?
- Operations: What costs arise from real-world deployment?
- Risk: How will the team detect performance issues?
- Recovery: Can the system mitigate potential failures before they escalate?
Final Thoughts on SGD and Adam
SGD and Adam represent structured mechanisms within broader sociotechnical frameworks. Their true value lies not in the name but in their ability to deliver concrete improvements under specified conditions. By adhering to a disciplined evaluation approach, these algorithms can emerge as robust tools in the realm of AI, facilitating informed decisions and operational accountability.
Certainly! Here are five FAQs based on the topic of how machine learning optimizers learn, inspired by the content from Unite.AI.
FAQ 1: What is a machine learning optimizer?
Answer: A machine learning optimizer is an algorithm that adjusts the parameters of a model to minimize loss and improve accuracy. It updates weights based on the gradients calculated from the loss function, guiding the model toward better performance during training.
FAQ 2: How do optimizers improve the learning process in machine learning?
Answer: Optimizers improve the learning process by efficiently navigating the error landscape. They adjust model parameters based on the gradients calculated during backpropagation, enabling faster convergence toward the optimal solution. Different optimizers employ various strategies to balance exploration and exploitation, often leading to better training outcomes.
FAQ 3: What are some common types of machine learning optimizers?
Answer: Common types of machine learning optimizers include:
- Stochastic Gradient Descent (SGD): Updates parameters using one sample at a time.
- Adam (Adaptive Moment Estimation): Combines momentum and scaling with adaptive learning rates for faster convergence.
- RMSprop: Adapts the learning rate based on recent gradients to maintain an optimal pace.
FAQ 4: What role does the learning rate play in optimization?
Answer: The learning rate determines the size of the step taken towards the minimum of the loss function during optimization. A high learning rate might cause the optimizer to overshoot, while a low learning rate can lead to slow convergence. Choosing an appropriate learning rate is crucial for effective training and can significantly impact the model’s performance.
FAQ 5: How do optimizers handle local minima in machine learning?
Answer: Many optimizers include mechanisms like momentum or adaptive learning rates to help escape local minima. By maintaining a velocity based on past gradients, optimizers like Adam and RMSprop can overcome shallow local minima and navigate more complex areas of the loss landscape, improving the chances of finding the global minimum.
Feel free to let me know if you need more information or specific details!
Related posts:
- Streamlining Geospatial Data for Machine Learning Experts: Microsoft’s TorchGeo Technology
- Utilizing Machine Learning to Forecast Market Trends in Real Estate through Advanced Analytics
- Here are some alternatives for the title: 1. “Enhance Your Understanding with These Homework Explanations – Unite.AI” 2. “Boost Your Learning with These Homework Insights – Unite.AI” 3. “Unlock Homework Success with These Helpful Explanations – Unite.AI” 4. “Discover How These Homework Explanations Can Help You – Unite.AI” 5. “Master Your Homework with These Insightful Explanations – Unite.AI” Let me know if you need more options!
- SpaceX’s Cloud Division Sees Revenue Triple Despite Ongoing Losses – Unite.AI
No comment yet, add your voice below!